
PDF to Word Conversion Quality: 24-File Test (2026)
Reproducible first-party product test
We submitted 24 controlled English PDFs to the live converter and inspected every returned DOCX. The service produced 22 downloadable outputs and 2 cases did not reach a downloadable result. This page publishes the method, per-file data, and source/output evidence.
Key results
In this run, 22 of 24 jobs reached the ready state and 22 outputs passed the DOCX package check. Across scored outputs, mean normalized character recall was 99.9% and mean token recall was 99.6%.
Editorial repair assessments: 0 ready without edits, 2 minor repair, 20 major repair, 2 failed.
Why PDF-to-Word results vary
A PDF commonly records where text, pictures, and vector graphics appear on a page without storing all of the relationships that make an editable document, such as paragraphs, tables, and columns. A converter must infer those relationships. Microsoft describes the same structural problem in its official guide, Opening PDFs in Word (source reviewed 2026-08-13).
This is why the test separates text retention from editable structure. A table can retain every visible word while still becoming plain paragraphs, and an image caption can survive even when the image itself is missing.
How we ran the 24-file test
The corpus contained 22 digital files, 2 scanned files. All were processed through one recorded live run; results were analyzed offline from the saved run log and returned files.
- We created a controlled corpus of 24 synthetic English PDFs with stable case IDs, source hashes, and matching ground-truth text files.
- Each file was submitted individually to the live PDF to Word converter. Job states, public errors, output hashes, and observed times were recorded.
- Every returned DOCX was checked as an OOXML package. The analyzer counted paragraphs, tables, cells, media, drawing objects, section properties, page-break signals, external relationships, and macro indicators.
- Extracted text was compared with the ground truth using the published normalization rules. Word page rendering was unavailable, so returned DOCX files were assessed from extracted text and measured OOXML structure rather than from Word screenshots.
The complete procedure, normalization profile, run metadata, and analyzer definitions are included in the downloadable methodology.
What each metric means
- Ready
- The live job reached the service state
ready. It does not mean the output needed no edits. - Character recall
- The share of normalized, non-space ground-truth characters found in the extracted DOCX text. It does not test reading order or layout.
- Token recall
- The share of normalized ground-truth tokens found in the output. It is based on token overlap and does not reward correct order.
- Word error rate
- An order-sensitive token edit distance divided by the number of ground-truth tokens. Lower is better; values can exceed 100%.
- Word structure
- Counts of actual OOXML elements such as tables, media, drawings, and page-break signals. These counts do not prove visual fidelity.
- Editorial repair assessment
- A structure-based label: ready without edits, minor repair, major repair, or failed. It is based on extracted text and measured OOXML structure, not a rendered Word page. The per-file note explains the decision.
Results by test category
Category averages are shown with their sample sizes. Digital-text files and image-only files remain separate so that one source type cannot hide the behavior of another.
| Category | Files | Ready | Valid DOCX | Character recall | Token recall | WER | With tables | With media | Median ready time |
|---|---|---|---|---|---|---|---|---|---|
| Columns | 2 | 2 | 2 | 100.0% | 100.0% | 86.2% | 0 | 0 | 21.58 s |
| Forms | 2 | 2 | 2 | 100.0% | 100.0% | 35.0% | 0 | 0 | 2.99 s |
| Headers Footers | 1 | 1 | 1 | 100.0% | 100.0% | 127.0% | 0 | 0 | 22.25 s |
| Headings | 1 | 1 | 1 | 100.0% | 100.0% | 26.5% | 0 | 0 | 2.65 s |
| Images | 1 | 1 | 1 | 100.0% | 100.0% | 70.0% | 0 | 0 | 2.35 s |
| Links | 2 | 2 | 2 | 100.0% | 100.0% | 61.0% | 0 | 0 | 26.18 s |
| Lists | 1 | 1 | 1 | 100.0% | 100.0% | 31.7% | 0 | 0 | 2.19 s |
| Mixed Layout | 1 | 1 | 1 | 100.0% | 100.0% | 25.0% | 0 | 0 | 4.20 s |
| Multipage | 1 | 1 | 1 | 100.0% | 100.0% | 188.9% | 0 | 0 | 2.49 s |
| Ocr | 2 | 0 | 0 | — | — | — | 0 | 0 | — |
| Page Geometry | 2 | 2 | 2 | 100.0% | 100.0% | 30.5% | 0 | 0 | 23.07 s |
| Plain Text | 1 | 1 | 1 | 100.0% | 100.0% | 25.6% | 0 | 0 | 4.00 s |
| Punctuation | 1 | 1 | 1 | 100.0% | 100.0% | 20.4% | 0 | 0 | 33.27 s |
| References | 1 | 1 | 1 | 100.0% | 100.0% | 31.6% | 0 | 0 | 40.69 s |
| Tables | 2 | 2 | 2 | 98.7% | 95.3% | 42.4% | 0 | 0 | 2.28 s |
| Technical Text | 1 | 1 | 1 | 100.0% | 100.0% | 46.4% | 0 | 0 | 2.47 s |
| Typography | 2 | 2 | 2 | 100.0% | 100.0% | 45.5% | 0 | 0 | 12.76 s |
All 24 file results
The table reports every case, including failures and analysis errors. A dash means that the metric could not be calculated; it does not mean zero.
| Case | Test | Category | Source | Job status | Character recall | Token recall | WER | Detected Word structure | Repair assessment | Review note |
|---|---|---|---|---|---|---|---|---|---|---|
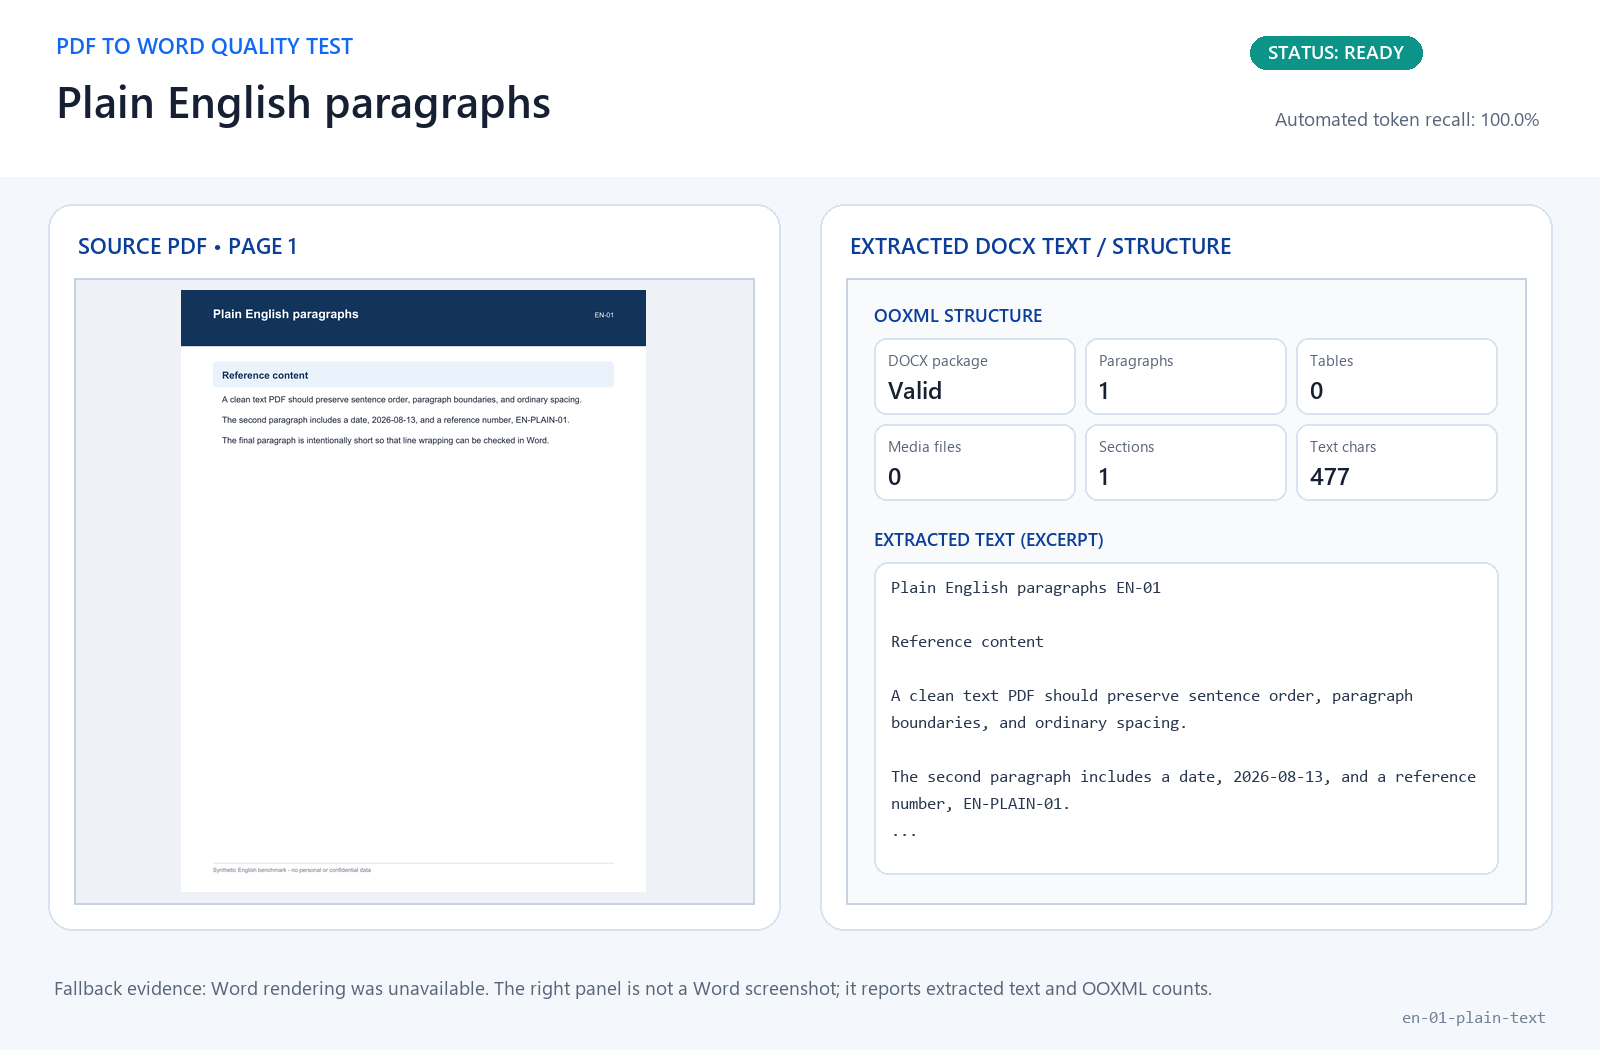
en-01-plain-text | Plain English paragraphs | Plain Text | Digital | Ready | 100.0% | 100.0% | 25.6% | Tables 0; media 0; page signals 0 | Minor repair | Text retention was high, but the returned document used one nonempty paragraph and needs paragraph and style review. |
en-02-mixed-fonts | Mixed font families and styles | Typography | Digital | Ready | 100.0% | 100.0% | 60.0% | Tables 0; media 0; page signals 0 | Major repair | The returned package was valid, but the main document stored the extracted content in a single nonempty paragraph. |
en-03-punctuation | Punctuation and symbols | Punctuation | Digital | Ready | 100.0% | 100.0% | 20.4% | Tables 0; media 0; page signals 0 | Minor repair | Text retention was high, but the returned document used one nonempty paragraph and needs paragraph and style review. |
en-04-urls-email | URLs and email addresses | Links | Digital | Ready | 100.0% | 100.0% | 40.7% | Tables 0; media 0; page signals 0 | Major repair | The text was returned, but OOXML inspection found no external relationships, so link behavior requires manual rebuilding and verification. |
en-05-lists | Ordered and unordered lists | Lists | Digital | Ready | 100.0% | 100.0% | 31.7% | Tables 0; media 0; page signals 0 | Major repair | The returned package was valid, but the main document stored the extracted content in a single nonempty paragraph. |
en-06-headings | Document heading hierarchy | Headings | Digital | Ready | 100.0% | 100.0% | 26.5% | Tables 0; media 0; page signals 0 | Major repair | The returned package was valid, but the main document stored the extracted content in a single nonempty paragraph. |
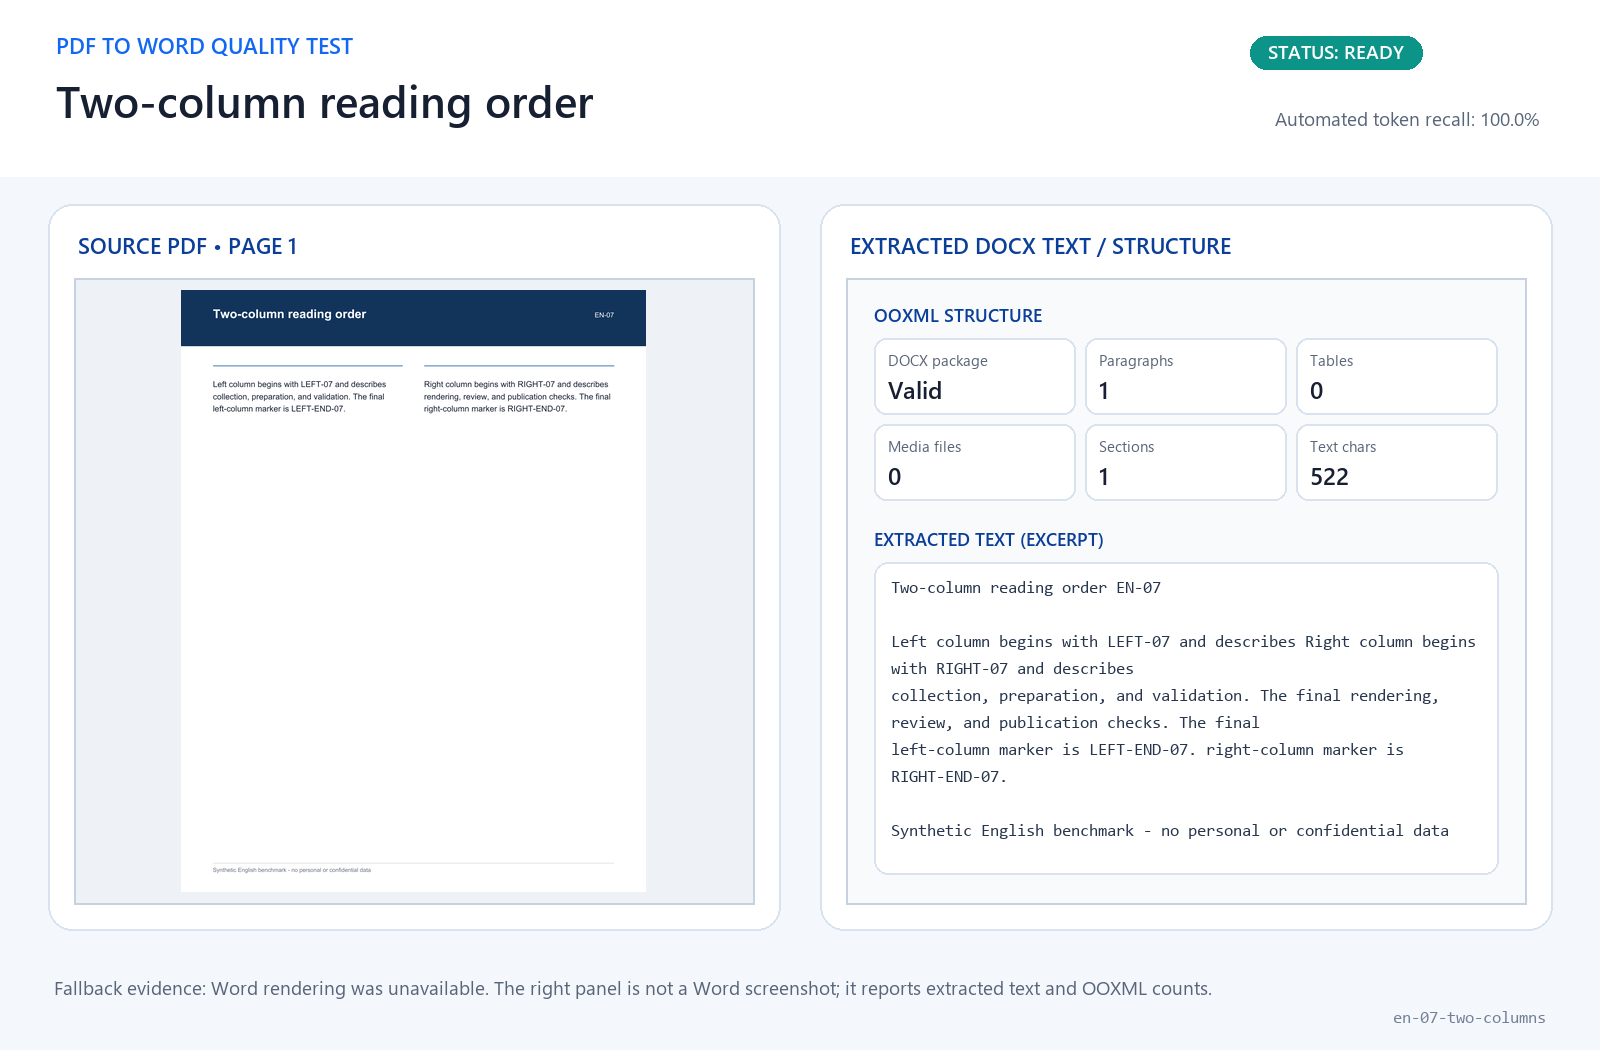
en-07-two-columns | Two-column reading order | Columns | Digital | Ready | 100.0% | 100.0% | 76.3% | Tables 0; media 0; page signals 0 | Major repair | The source used multiple layout regions, but the returned DOCX stored the content in one nonempty paragraph with no editable column structure. |
en-08-three-columns | Three-column project brief | Columns | Digital | Ready | 100.0% | 100.0% | 96.2% | Tables 0; media 0; page signals 0 | Major repair | The source used multiple layout regions, but the returned DOCX stored the content in one nonempty paragraph with no editable column structure. |
en-09-simple-table | Simple inventory table | Tables | Digital | Ready | 100.0% | 100.0% | 36.0% | Tables 0; media 0; page signals 0 | Major repair | The visible source structure was not returned as an editable Word table; OOXML inspection found zero table objects. |
en-10-complex-table | Complex service table | Tables | Digital | Ready | 97.3% | 90.7% | 48.8% | Tables 0; media 0; page signals 0 | Major repair | The visible source structure was not returned as an editable Word table; OOXML inspection found zero table objects. |
en-11-headers-footers | Headers and footers across pages | Headers Footers | Digital | Ready | 100.0% | 100.0% | 127.0% | Tables 0; media 0; page signals 1 | Major repair | The returned package was valid and exposed 1 page-break signals, but editable structure still needs reconstruction. |
en-12-typography | Typography and emphasis | Typography | Digital | Ready | 100.0% | 100.0% | 31.0% | Tables 0; media 0; page signals 0 | Major repair | The returned package was valid, but the main document stored the extracted content in a single nonempty paragraph. |
en-13-multipage | Three-page operations report | Multipage | Digital | Ready | 100.0% | 100.0% | 188.9% | Tables 0; media 0; page signals 2 | Major repair | The returned package was valid and exposed 2 page-break signals, but editable structure still needs reconstruction. |
en-14-landscape | Landscape capacity schedule | Page Geometry | Digital | Ready | 100.0% | 100.0% | 23.1% | Tables 0; media 0; page signals 0 | Major repair | The returned package was valid, but the main document stored the extracted content in a single nonempty paragraph. |
en-15-rotated-90 | Rotated page test | Page Geometry | Digital | Ready | 100.0% | 100.0% | 37.9% | Tables 0; media 0; page signals 0 | Major repair | The returned package was valid, but the main document stored the extracted content in a single nonempty paragraph. |
en-16-technical-identifiers | Technical identifiers | Technical Text | Digital | Ready | 100.0% | 100.0% | 46.4% | Tables 0; media 0; page signals 0 | Major repair | The returned package was valid, but the main document stored the extracted content in a single nonempty paragraph. |
en-17-image-caption | Embedded process diagram | Images | Digital | Ready | 100.0% | 100.0% | 70.0% | Tables 0; media 0; page signals 0 | Major repair | The source included visual content, but OOXML inspection found zero embedded media files in the returned DOCX. |
en-18-interactive-form | Interactive review form | Forms | Digital | Ready | 100.0% | 100.0% | 45.0% | Tables 0; media 0; page signals 0 | Major repair | The visible source structure was not returned as an editable Word table; OOXML inspection found zero table objects. |
en-19-invoice | Synthetic service invoice | Forms | Digital | Ready | 100.0% | 100.0% | 25.0% | Tables 0; media 0; page signals 0 | Major repair | The visible source structure was not returned as an editable Word table; OOXML inspection found zero table objects. |
en-20-footnotes | Footnotes and references | References | Digital | Ready | 100.0% | 100.0% | 31.6% | Tables 0; media 0; page signals 0 | Major repair | The returned package was valid, but the main document stored the extracted content in a single nonempty paragraph. |
en-21-hyperlinks | Internal and external hyperlinks | Links | Digital | Ready | 100.0% | 100.0% | 81.2% | Tables 0; media 0; page signals 1 | Major repair | The text was returned, but OOXML inspection found no external relationships, so link behavior requires manual rebuilding and verification. |
en-22-mixed-layout | Mixed layout report | Mixed Layout | Digital | Ready | 100.0% | 100.0% | 25.0% | Tables 0; media 0; page signals 0 | Major repair | The source used multiple layout regions, but the returned DOCX stored the content in one nonempty paragraph with no editable column structure. |
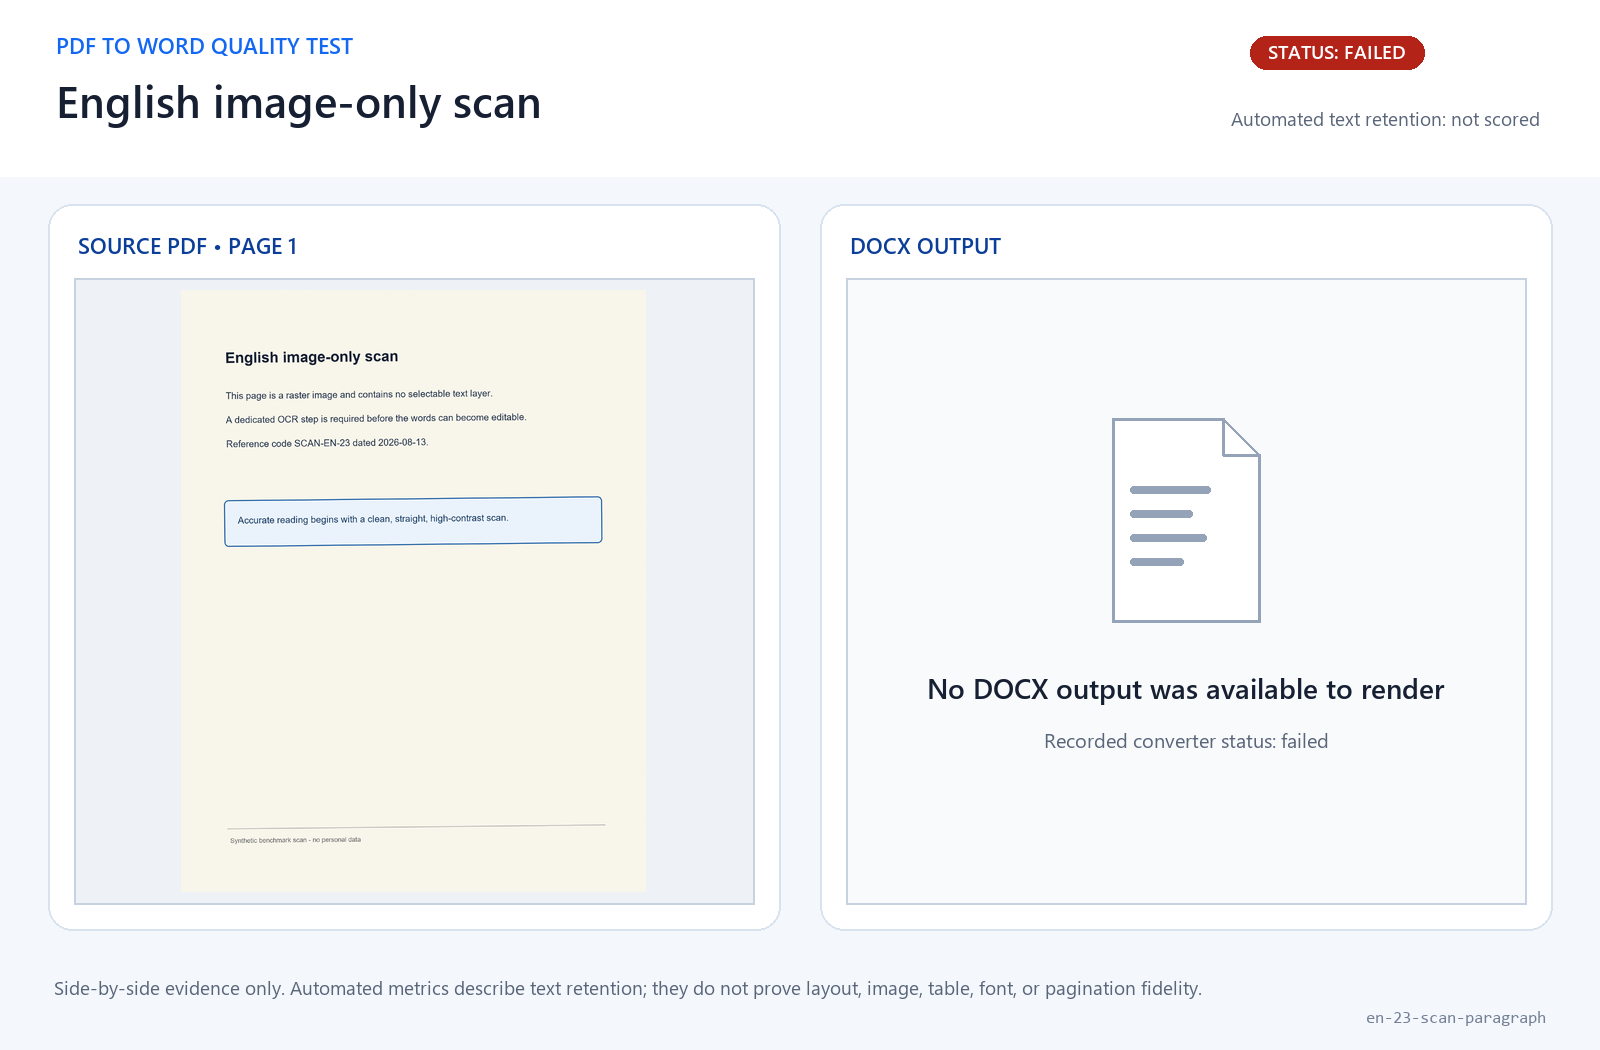
en-23-scan-paragraph | English image-only scan | Ocr | Scanned | Failed | — | — | — | Tables 0; media 0; page signals 0 | Failed | The live job failed and no DOCX was returned; the source was an image-only scan that requires OCR. |
en-24-scan-table | English image-only table scan | Ocr | Scanned | Failed | — | — | — | Tables 0; media 0; page signals 0 | Failed | The live job failed and no DOCX was returned; the source was an image-only scan that requires OCR. |
Source and DOCX structure evidence
Each composite shows a rendered source PDF page beside extracted DOCX text and measured OOXML structure. These are not before-and-after Word screenshots and do not establish final Word page appearance.
Plain-text extraction
Two-column reading order
Simple table structure
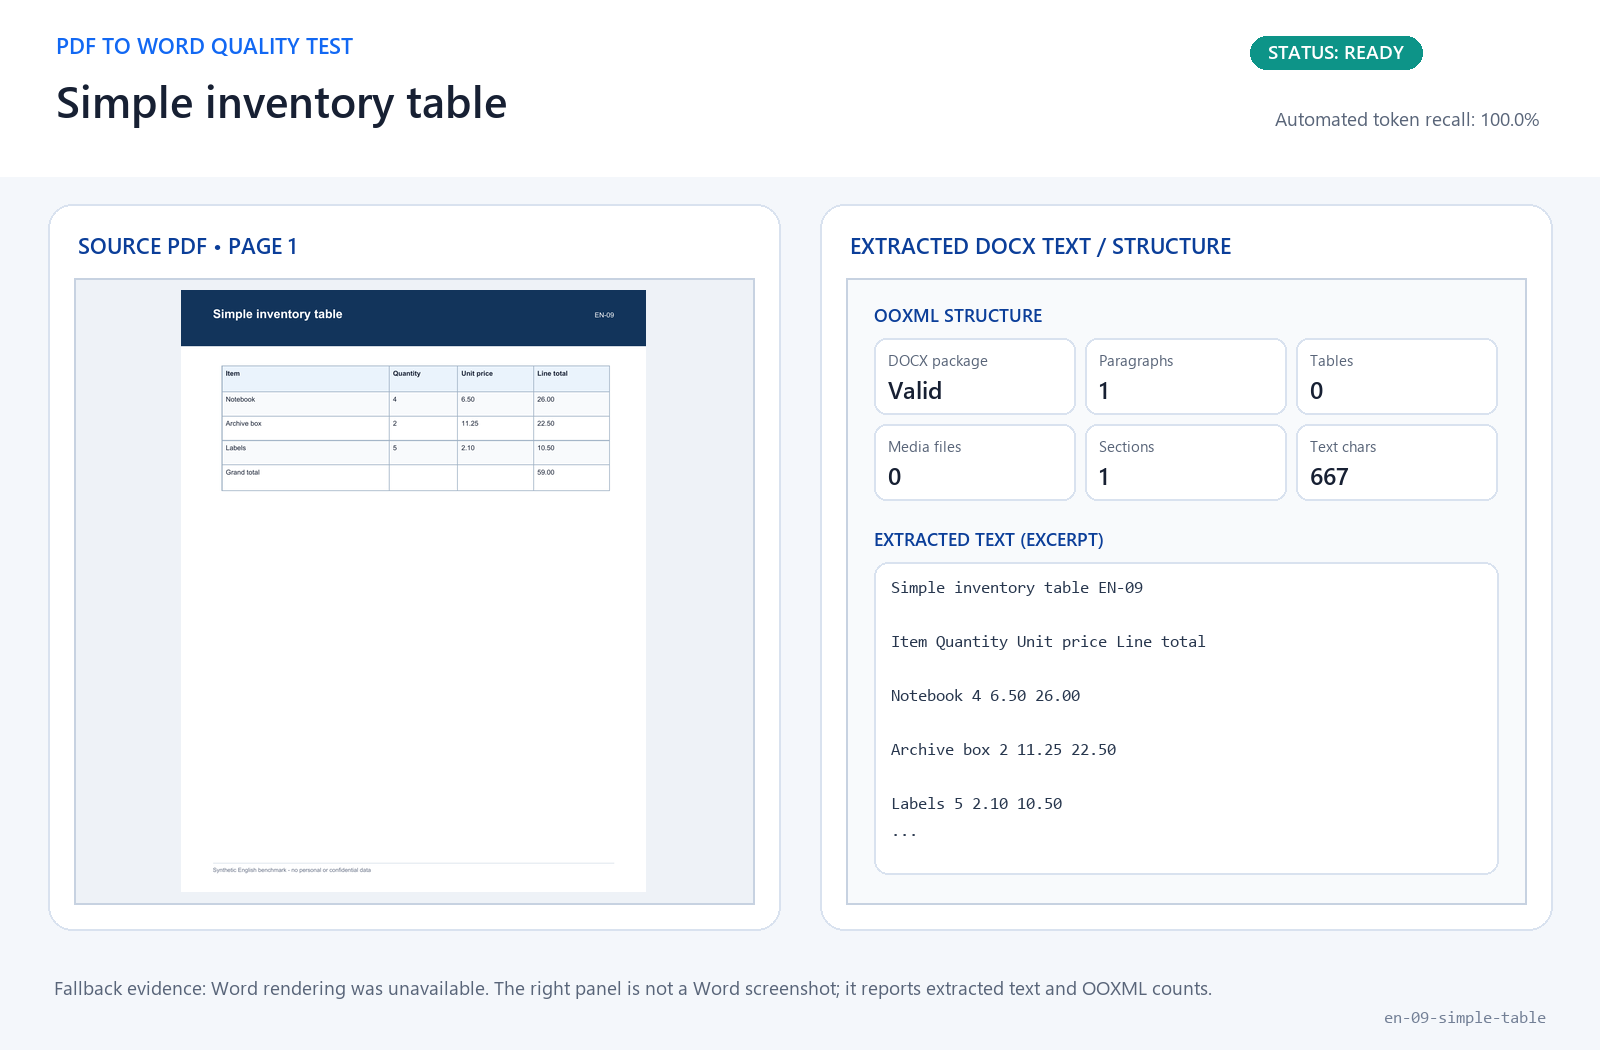
Image and caption
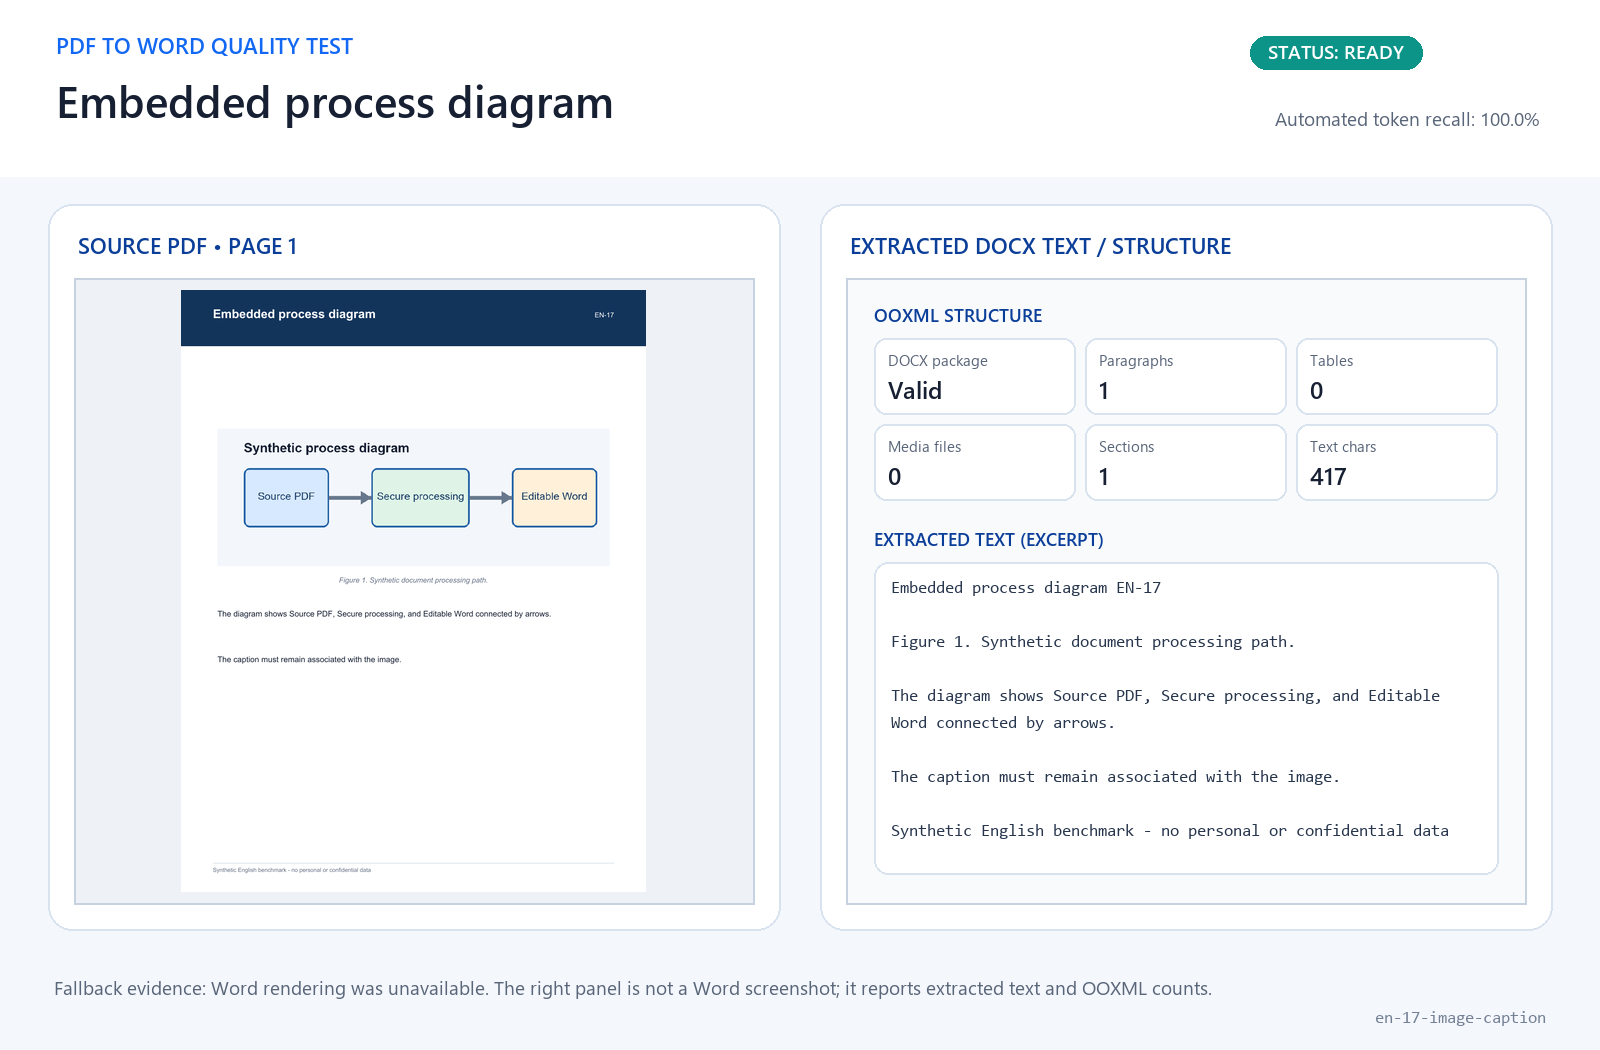
Image-only scan
Limitations and interpretation
- This is a controlled engineering sample of 24 synthetic files, not an estimate for every English PDF on the web.
- The findings describe the recorded live run and converter version. They are not a permanent service-level guarantee.
- Timing includes the observed workflow and may reflect upload, queue, conversion, polling, and download overhead.
- Text recall does not measure page geometry, typography, reading order, editability, or image quality.
- OOXML element counts identify document structure but do not prove that it looks correct in every Word version or operating system.
- The package checks report external relationships and macro indicators. They are not a malware certification.
- Image-only files test the live service response for files without an embedded text layer. They do not evaluate every scanning condition or image quality level.
- Editorial repair assessments involve judgment and are based on extracted text and OOXML structure because Word page rendering was unavailable. They do not establish visual fidelity in Word.
Download the files and results
Use the CSV for direct per-file results. The versioned publication bundle contains the complete JSON results and reproducibility files; the checksum ledger identifies the exact packaged files used in this run.